仮想カラム
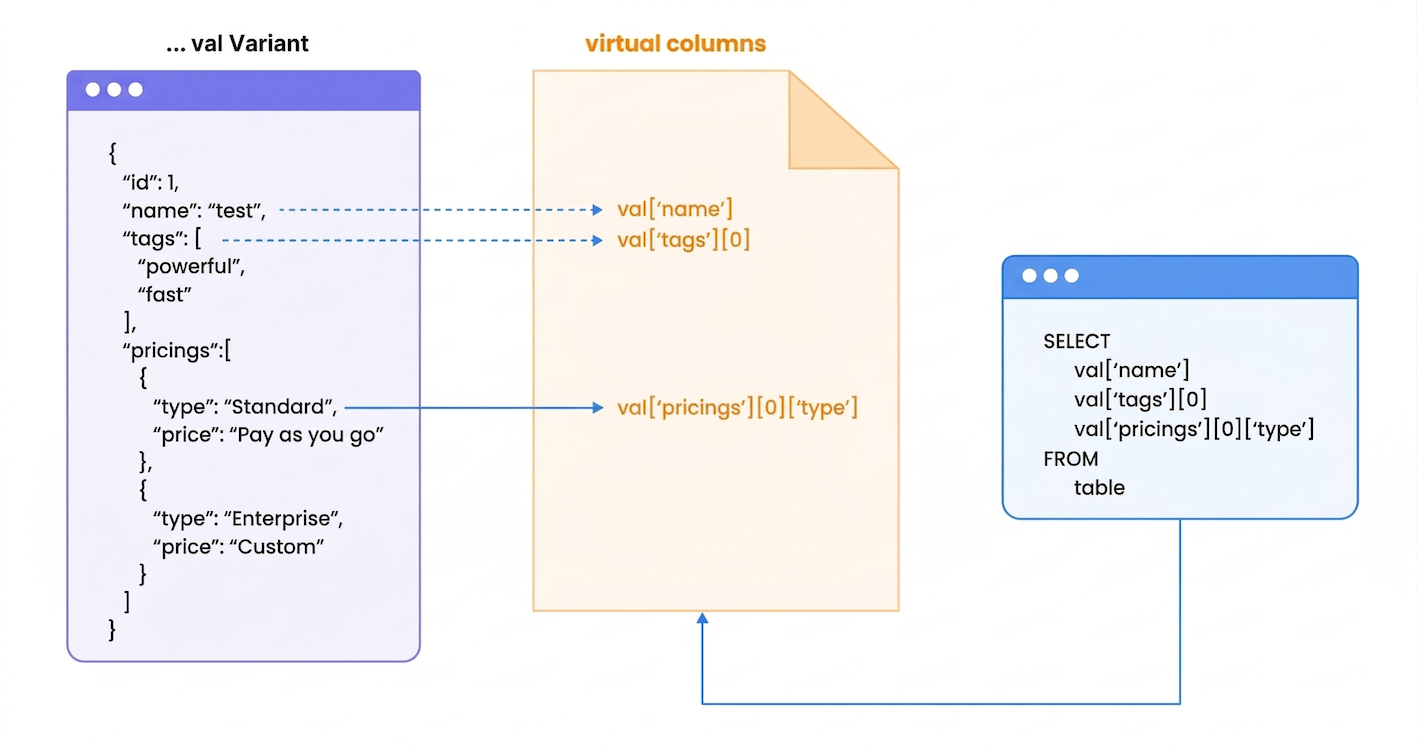
仮想カラムは、VARIANT カラムに格納された半構造化データに対するクエリを自動的に高速化します。この機能は、JSON データアクセスに対して設定不要のパフォーマンス最適化を提供します。
どのような問題を解決するのか
JSON データをクエリする際、従来のデータベースではネストされたフィールドにアクセスするたびに JSON 構造全体を解析する必要があります。これにより、次のようなパフォーマンス上のボトルネックが発生します。
シナリオ例: 商品データを JSON 形式で保持する e コマース分析テーブルを考えます。仮想カラムがない場合、数百万行に対して product_data['category'] をクエリするには、すべての JSON ドキュメントを解析する必要があります。仮想カラムを使用すると、これは直接的なカラム参照になります。
自動的に動作する仕組み
- データ取り込み → TiDB Cloud Lake が VARIANT カラム内の JSON 構造を分析します
- スマート検出 → システムが頻繁にアクセスされるネストフィールドを特定します
- バックグラウンド最適化 → 仮想カラムが自動的に作成されます
- クエリ高速化 → クエリは自動的に最適化されたパスを使用します
設定
仮想カラムは v1.2.832 以降でデフォルトで有効になっており、追加の設定は不要です。
完全な例
この例では、自動的な仮想カラムの作成とパフォーマンス上の利点を示します。
-- Create a table named 'test' with columns 'id' and 'val' of type Variant.
CREATE TABLE test(id int, val variant);

-- Insert sample records into the 'test' table with Variant data.
INSERT INTO
  test
VALUES
  (
    1,
    '{"id":1,"name":"datalake","tags":["powerful","fast"],"pricings":[{"type":"Standard","price":"Pay as you go"},{"type":"Enterprise","price":"Custom"}]}'
  ),
  (
    2,
    '{"id":2,"name":"databricks","tags":["scalable","flexible"],"pricings":[{"type":"Free","price":"Trial"},{"type":"Premium","price":"Subscription"}]}'
  ),
  (
    3,
    '{"id":3,"name":"snowflake","tags":["cloud-native","secure"],"pricings":[{"type":"Basic","price":"Pay per second"},{"type":"Enterprise","price":"Annual"}]}'
  ),
  (
    4,
    '{"id":4,"name":"redshift","tags":["reliable","scalable"],"pricings":[{"type":"On-Demand","price":"Pay per usage"},{"type":"Reserved","price":"1 year contract"}]}'
  ),
  (
    5,
    '{"id":5,"name":"bigquery","tags":["innovative","cost-efficient"],"pricings":[{"type":"Flat Rate","price":"Monthly"},{"type":"Flex","price":"Per query"}]}'
  );

INSERT INTO test SELECT * FROM test;
INSERT INTO test SELECT * FROM test;
INSERT INTO test SELECT * FROM test;
INSERT INTO test SELECT * FROM test;
INSERT INTO test SELECT * FROM test;

-- Explain the query execution plan for selecting specific fields from the table.
EXPLAIN
SELECT
  val ['name'],
  val ['tags'] [0],
  val ['pricings'] [0] ['type']
FROM
  test;

-[ EXPLAIN ]-----------------------------------
Exchange
├── output columns: [test.val['name'] (#3), test.val['pricings'][0]['type'] (#5), test.val['tags'][0] (#8)]
├── exchange type: Merge
└── TableScan
    ├── table: default.default.test
    ├── output columns: [val['name'] (#3), val['pricings'][0]['type'] (#5), val['tags'][0] (#8)]
    ├── read rows: 160
    ├── read size: 1.69 KiB
    ├── partitions total: 6
    ├── partitions scanned: 6
    ├── pruning stats: [segments: <range pruning: 6 to 6>, blocks: <range pruning: 6 to 6>]
    ├── push downs: [filters: [], limit: NONE]
    ├── virtual columns: [val['name'], val['pricings'][0]['type'], val['tags'][0]]
    └── estimated rows: 160.00

-- Explain the query execution plan for selecting only the 'name' field from the table.
EXPLAIN
SELECT
  val ['name']
FROM
  test;

-[ EXPLAIN ]-----------------------------------
Exchange
├── output columns: [test.val['name'] (#2)]
├── exchange type: Merge
└── TableScan
    ├── table: default.book_db.test
    ├── output columns: [val['name'] (#2)]
    ├── read rows: 160
    ├── read size: < 1 KiB
    ├── partitions total: 16
    ├── partitions scanned: 16
    ├── pruning stats: [segments: <range pruning: 6 to 6>, blocks: <range pruning: 16 to 16>]
    ├── push downs: [filters: [], limit: NONE]
    ├── virtual columns: [val['name']]
    └── estimated rows: 160.00

-- Display all the auto generated virtual columns.
SHOW VIRTUAL COLUMNS WHERE table='test';

╭────────────────────────────────────────────────────────────────────────────────────────────────────────╮
│ database │  table │ source_column │ virtual_column_id │    virtual_column_name   │ virtual_column_type │
│  String  │ String │     String    │       UInt32      │          String          │        String       │
├──────────┼────────┼───────────────┼───────────────────┼──────────────────────────┼─────────────────────┤
│ default  │ test   │ val           │        3000000000 │ ['id']                   │ UInt64              │
│ default  │ test   │ val           │        3000000001 │ ['name']                 │ String              │
│ default  │ test   │ val           │        3000000002 │ ['pricings'][0]['price'] │ String              │
│ default  │ test   │ val           │        3000000003 │ ['pricings'][0]['type']  │ String              │
│ default  │ test   │ val           │        3000000004 │ ['pricings'][1]['price'] │ String              │
│ default  │ test   │ val           │        3000000005 │ ['pricings'][1]['type']  │ String              │
│ default  │ test   │ val           │        3000000006 │ ['tags'][0]              │ String              │
│ default  │ test   │ val           │        3000000007 │ ['tags'][1]              │ String              │
╰────────────────────────────────────────────────────────────────────────────────────────────────────────╯
監視コマンド
パフォーマンス結果
仮想カラムは通常、次の利点を提供します。
- 5~10 倍高速な JSON フィールドアクセス
- クエリ変更なしの自動最適化
- クエリ処理中のリソース消費の削減
- 既存アプリケーションに対する透過的な高速化
仮想カラムはバックグラウンドで自動的に動作し、TiDB Cloud Lake が設定不要で JSON クエリを最適化します。